by
Aditya Parameswaran
on Jun 25, 2018 | Categories:
Analytics, data exploration, Databases
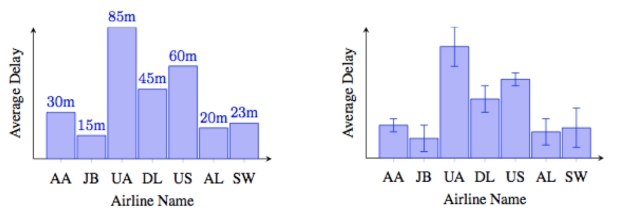
Information visualization is an essential tool in the arsenal of a data scientist: visualizations help identify trends and patterns, spot outliers and anomalies, and verify hypotheses. Moreover, visualizations are visceral and intuitive: they tell us stories about our data; they educate, delight,…
Read more…
by
Ihab Ilyas
on Apr 18, 2018 | Categories:
Big Data, Machine Learning, Systems
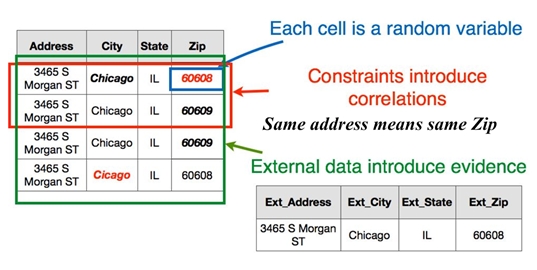
When dealing with real-world data, dirty data is the norm rather than the exception. We continuously need to predict correct values, impute missing ones, and find links between various data artefacts such as schemas and records. We need to stop treating data cleaning as a piecemeal exercise…
Read more…
by
Melanie Herschel and Yannis Velegrakis
on Mar 22, 2018 | Categories:
Big Data, data exploration, Interview
We are witnessing data of unprecedented volume, variety and velocity. Such data is collected from almost every aspect of human activity and stored in large repositories in order to be later analyzed and turned into useful insights. The storage model is not any more the one in which data is placed…
Read more…
by
Georgia Koutrika
on Mar 10, 2018 | Categories:
Uncategorized
José Alfredo Blakeley, Partner Architect at Microsoft, passed away on January 7th, 2018. With this “tribute”, we would like to honor his many contributions to data management. José will be sorely missed as a great scientist, mentor, colleague, and friend. José completed his undergraduate studies at…
Read more…
by
Azza Abouzied and Paolo Papotti
on Feb 14, 2018 | Categories:
Big Data, Databases, Interview, Machine Learning
The web is an ever-evolving source of information, with data and knowledge derived from it powering a great range of modern applications. Accompanying the huge wealth of information, web data also introduces numerous challenges due to its size, diversity, volatility, inaccuracy, and contradictions.…
Read more…
by
Arijit Khan and Yinghui Wu
on Jun 16, 2017 | Categories:
Graph Queries
Graphs are a ubiquitous model to represent objects and their relations. Examples include communication and computer systems, the World Wide Web, online social networks, biological networks, transportation systems, epidemic networks, chemical networks, and hidden terrorist networks. All these…
Read more…
by
Surajit Chaudhuri
on May 12, 2017 | Categories:
Big Data, Query Processing
I think we need to take a hard look at approximate query processing. Don’t get me wrong. The vision of approximate query processing is indeed compelling. In the age of Big Data, the ability to answer analytic queries “approximately”, but at a fraction of the cost of executing the query in the…
Read more…
by
Vijay Srinivas Agneeswaran
on Apr 27, 2017 | Categories:
Big Data, Databases
Google has recently announced that its flagship wide-area database named Spanner has been made available on the Google Cloud. Google Spanner is the next generation globally-distributed database built inside Google and announced to the world through the paper published in OSDI 2012 [1]. This article…
Read more…
by
Donald Kossmann
on Feb 22, 2017 | Categories:
Uncategorized
Dear SIGMOD/PODS Community: We are pleased to announce that the SIGMOD/PODS Conference 2017 will be held in Chicago in the week of May 14, 2017. We would like to thank all who helped us to find a new venue at such short notice. There were many suggestions, and many people helped investigate…
Read more…
by
Jignesh Patel
on Feb 9, 2017 | Categories:
Big Data, data exploration, Databots
The big data era (now more than a decade old) ushered in dramatic shift in mentality whereby enterprises increased their appetite for making “data-driven” decisions. To a large extent, most enterprises have gotten very good at collecting data. Now, the next big challenge is to unlock non-trivial…
Read more…