Category: Databases

by
Ibrahim Sabek
on Sep 21, 2026 | Categories:
Databases, Systems
Quantum computing might be the most famous technology that almost nobody has actually used. It shows up in movie plots, in nervous headlines about “the end of encryption,” and in the occasional promise that it will soon cure diseases, design new materials, and untangle city traffic, all at once. If…
Read more…
by
Eugene Wu
on Jul 4, 2025 | Categories:
Databases
Date: Thursday, June 26, 2025 Organizers: Eugene Wu, Raul Castro Fernandez Panelists: Overview As organizers, we aimed to foster a bottom-up discussion on the evolving role and future direction of academic database research. Motivated by seismic technological and budgetary shifts, particularly the…
Read more…
by
Eugene Wu
on Oct 10, 2024 | Categories:
Databases, Machine Learning
The past few years of generative AI have upended research agendas across academia. Having just spent my sabbatical in the Bay Area, where the San Francisco fog is mixed with a tinge of forest fire and LLMs, I wanted to reflect on the role of the academic database research community within this sea…
Read more…
by
Kyle Deeds and Ziniu Wu
on Sep 13, 2023 | Categories:
Databases, Query Processing
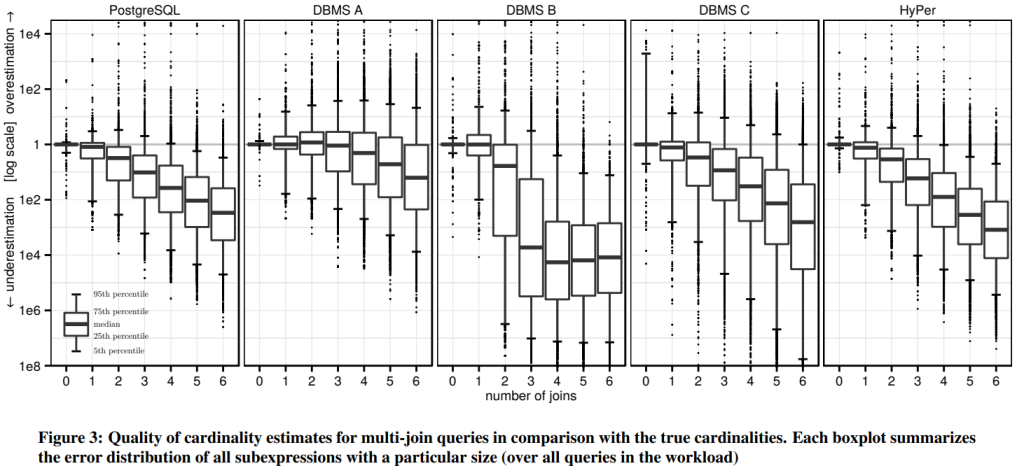
Introduction In the last decade, the database community has identified cardinality estimation as the primary stumbling block for modern query optimizers. Cardinality estimates, which estimate the size of sub-plan queries, are the primary basis for choosing between query plans, so poor estimates may…
Read more…
by
Mohamed Sharaf
on Feb 16, 2023 | Categories:
data exploration, Databases, Recommendations, Visualization
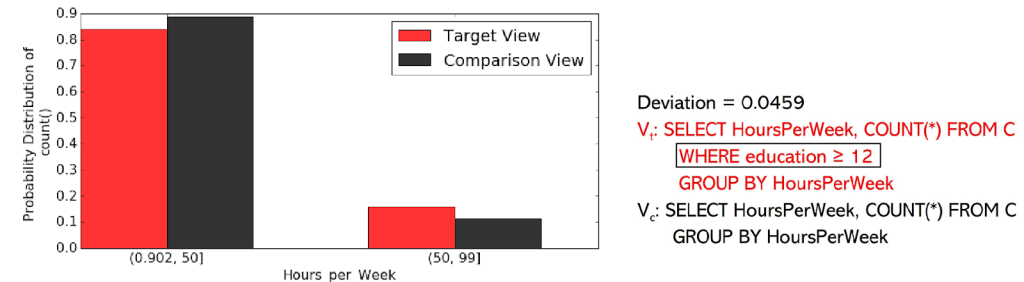
In this blog, we discuss the potential benefits of augmenting automated view recommendation solutions with query refinement techniques towards achieving insightful data exploration. Particularly, effective data exploration has been fueled by many approaches that rely on either view recommendation…
Read more…
by
Boris Glavic
on Jan 24, 2023 | Categories:
Analytics, Data Preparation, Databases
Uncertainty arises naturally in many application domains due to measurement errors, human error in data entry or transformation, missing data and bias in data collection, and many other reasons. When uncertainty is ignored during data preprocessing and analysis, this leads to hard to trace errors…
Read more…
by
Kian-Lee Tan
on Jun 10, 2022 | Categories:
Databases
In 2009, we wrote an article highlighting some database challenges in a co-space environment [1]. In such an environment, the physical space and the digital space co-exist in a “universe” and applications can manipulate the data flow within and across the two spaces. 13 years have since passed and…
Read more…
by
Sebastian Link
on May 10, 2022 | Categories:
Big Data, Databases
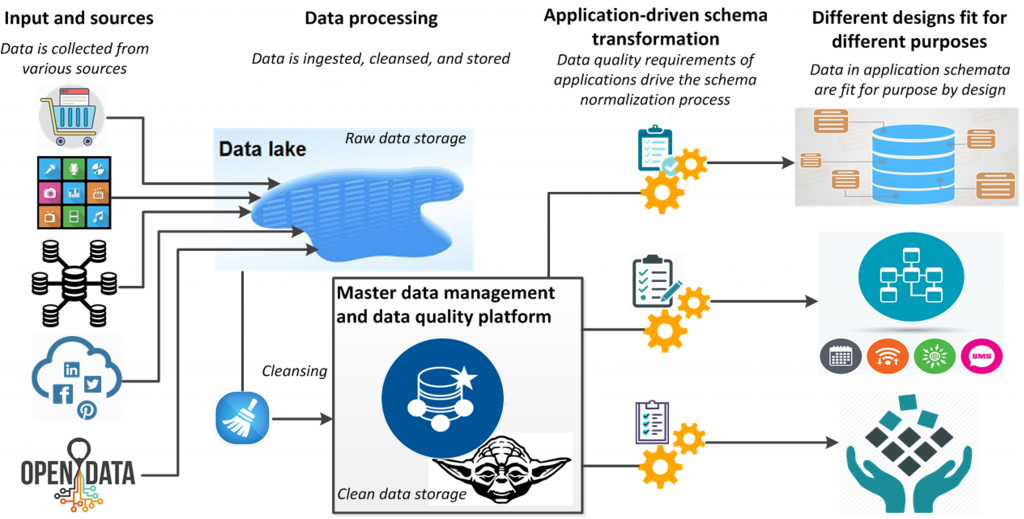
Financially, poor data quality costs organizations some ludicrous amounts of money. Worse, poor data quality is a strong inhibitor to the success of data science: No analytical method can create value from poor quality data. As a consequence, data science projects invest a majority of their…
Read more…
by
Kurt Stockinger
on Jun 20, 2019 | Categories:
data exploration, Databases, Search
The vision of natural language interfaces to databases (NLIDBs) is to make data stores more accessible for a wide range of non-tech savvy end users with the ultimate goal to talk to a database (almost) like to a human. While initially the database community focused on relational databases, there is…
Read more…
by
Arun Kumar
on Aug 21, 2018 | Categories:
Databases, Machine Learning
Overview of DEEM 2018 The ACM SIGMOD Second Workshop on Data Management for End-to-End Machine Learning (DEEM) was successfully held last June in Houston, TX. The goal of DEEM is to bring together researchers and practitioners at the intersection of applied machine learning (ML) and data…
Read more…
by
Aditya Parameswaran
on Jun 25, 2018 | Categories:
Analytics, data exploration, Databases
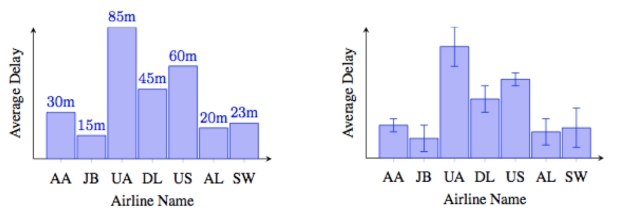
Information visualization is an essential tool in the arsenal of a data scientist: visualizations help identify trends and patterns, spot outliers and anomalies, and verify hypotheses. Moreover, visualizations are visceral and intuitive: they tell us stories about our data; they educate, delight,…
Read more…
by
Azza Abouzied and Paolo Papotti
on Feb 14, 2018 | Categories:
Big Data, Databases, Interview, Machine Learning
The web is an ever-evolving source of information, with data and knowledge derived from it powering a great range of modern applications. Accompanying the huge wealth of information, web data also introduces numerous challenges due to its size, diversity, volatility, inaccuracy, and contradictions.…
Read more…
by
Vijay Srinivas Agneeswaran
on Apr 27, 2017 | Categories:
Big Data, Databases
Google has recently announced that its flagship wide-area database named Spanner has been made available on the Google Cloud. Google Spanner is the next generation globally-distributed database built inside Google and announced to the world through the paper published in OSDI 2012 [1]. This article…
Read more…
by
Mohamed Mokbel
on Oct 6, 2016 | Categories:
Databases, Recommendations, Spatial, Systems
Self-driving cars, ride-sharing service (e.g., Uber and Lyft), and Pokemon Go are just three examples of recent disruptive applications that gained huge market share and publicity. It is expected that each self-driving car will generate 2 PB of data per year, with 10 Million of such cars by 2020.…
Read more…
by
Michael Stonebraker
on Jul 13, 2015 | Categories:
Databases
A Federated DBMS is a middleware offering that runs on top of (perhaps several) local DBMSs and presents a seamless interface to disparate systems with (perhaps) independently constructed DBMS schemas. Systems in this category include R*, Ingres*, Garlic, IBM’s Information Integrator, and several…
Read more…

by
Guy Lohman
on Apr 10, 2014 | Categories:
Databases
Is Query Optimization a “solved” problem? If not, are we attacking the “right” problems? How should we identify the “right” problems to solve? I asked these same questions almost exactly 25 years ago, in an extended abstract for a Workshop on Database Query Optimization that was organized by the…
Read more…
by
Philip A. Bernstein
on Feb 24, 2014 | Categories:
Databases
After hanging out exclusively with the database community for 35+ years, I’ve recently become more involved with the systems research community. I have a few observations and recommendations to share.Much of the work published in systems conferences covers topics that would have a natural home in…
Read more…
by
Arnab Nandi
on Dec 11, 2013 | Categories:
Databases
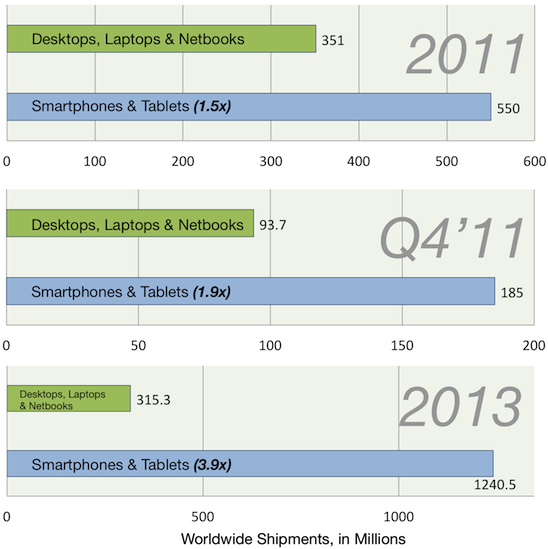
In 2011, I was traveling on the Kolkata Metro when I made an interesting observation. Nearly every passenger around me was using a computing device of some sort. Some were playing with their smartphones, some with their tablets, some listening to music on their iPod Touches. Each was a consumer of…
Read more…
by
Maurizio Lenzerini
on May 14, 2013 | Categories:
Databases
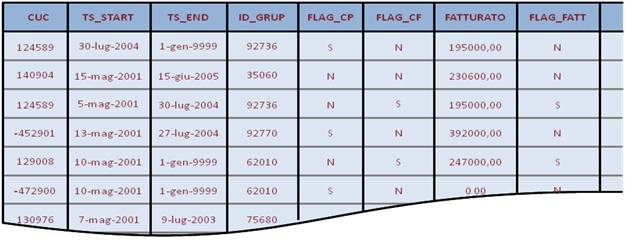
Figure 1 shows a portion of a relational table contained in a real, large information system. The table concerns the customers of an organization, where each row stores data about a single customer. The first column contains her code (if the code is negative, then the record refers to a special…
Read more…
by
Gerhard Weikum
on Mar 6, 2013 | Categories:
Big Data, Databases, Publication policy
Big Data should be Interesting Data! There are various definitions of Big Data; most center around a number of V’s like volume, velocity, variety, veracity – in short: interesting data (interesting in at least one aspect). However, when you look into research papers on Big Data, in SIGMOD, VLDB, or…
Read more…
by
Thomas Haigh
on Dec 11, 2012 | Categories:
Databases, History
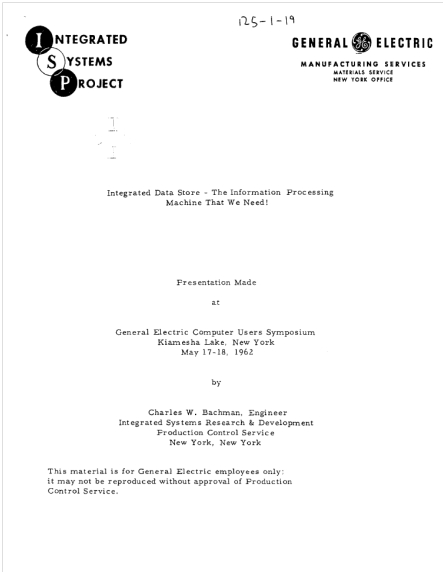
Fifty years ago a small team working to automate the business processes of the General Electric Low Voltage Switch Gear Department in Philadelphia built the first functioning prototype of a database management system. The Integrated Data Store was designed by Charles W. Bachman, who later won the…
Read more…