by
Mohamed Sharaf
on Feb 16, 2023 | Categories:
data exploration, Databases, Recommendations, Visualization
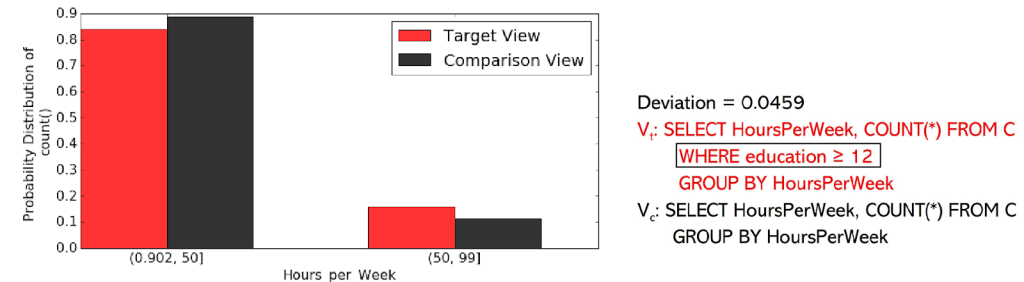
In this blog, we discuss the potential benefits of augmenting automated view recommendation solutions with query refinement techniques towards achieving insightful data exploration. Particularly, effective data exploration has been fueled by many approaches that rely on either view recommendation…
Read more…
by
Boris Glavic
on Jan 24, 2023 | Categories:
Analytics, Data Preparation, Databases
Uncertainty arises naturally in many application domains due to measurement errors, human error in data entry or transformation, missing data and bias in data collection, and many other reasons. When uncertainty is ignored during data preprocessing and analysis, this leads to hard to trace errors…
Read more…
by
karimaechihabi
on Dec 29, 2022 | Categories:
Data Science
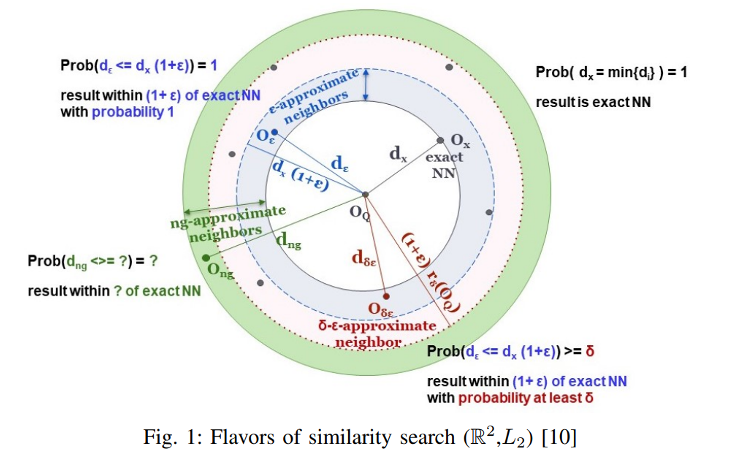
Similarity search is a fundamental building block for a myriad of critical data science applications involving large collections of high-dimensional objects, including data discovery, data cleaning, information retrieval, classification, outlier detection and clustering. Similarity search finds…
Read more…

by
Senjuti Basu Roy
on Oct 26, 2022 | Categories:
Recommendations
Given a large number of users’ preferences (numerical or ordinal scores, ranked order) over a large number of objects, returning top-k results entails selecting a small list/set containing exactly k objects that are most “appropriate “. In this article, I will investigate two alternatives for…
Read more…
by
Zhifeng Bao
on Sep 17, 2022 | Categories:
Big Data, Spatial
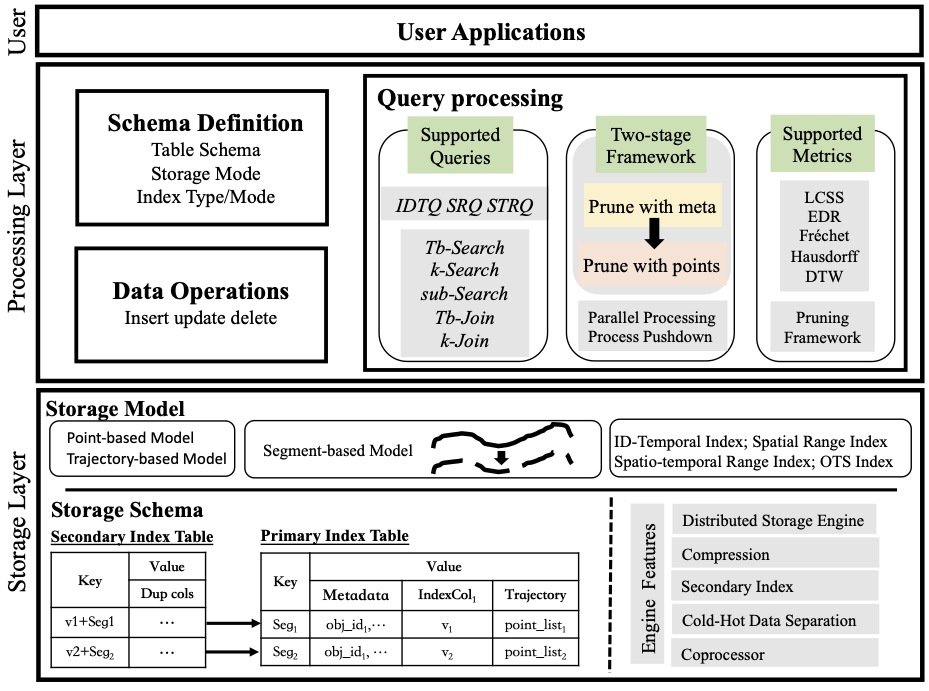
The sheer volume, variety, and velocity of data in this modern era have enabled significant advancements in many research areas. However, the advancements in the research community thanks to Big Data do not necessarily translate to the benefit of society; of ordinary people living ordinary lives.…
Read more…
by
Themis Palpanas
on Aug 25, 2022 | Categories:
Data Series
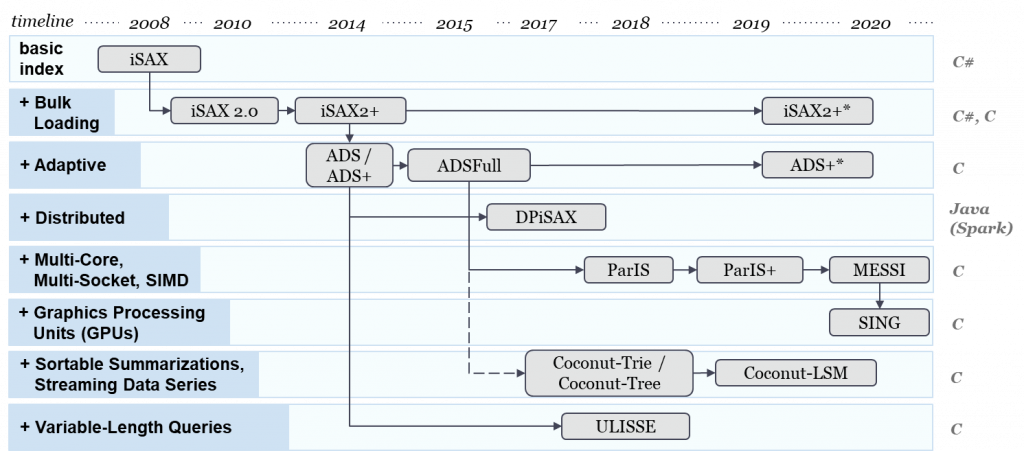
In this post, we motivate the need for efficient and effective solutions for data series similarity search, and we briefly present the work that has been done in this direction by the data series community. We also discuss the relationship to high-dimensional (high-d) vectors and deep neural…
Read more…
by
Azza Abouzied
on Aug 3, 2022 | Categories:
Decision Making, Epidemics
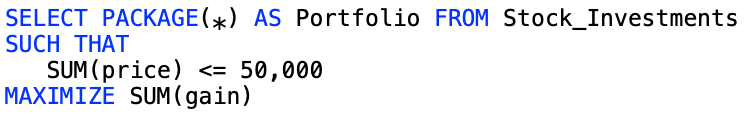
We built a tool, EpiPolicy, to help policy-makers better plan interventions to combat epidemics [13]. It was an eye-opening experience, where through collaborations and interviews with teams of epidemiologists, public health officials, and economists, we understood some of the complexities of…
Read more…
by
Kian-Lee Tan
on Jun 10, 2022 | Categories:
Databases
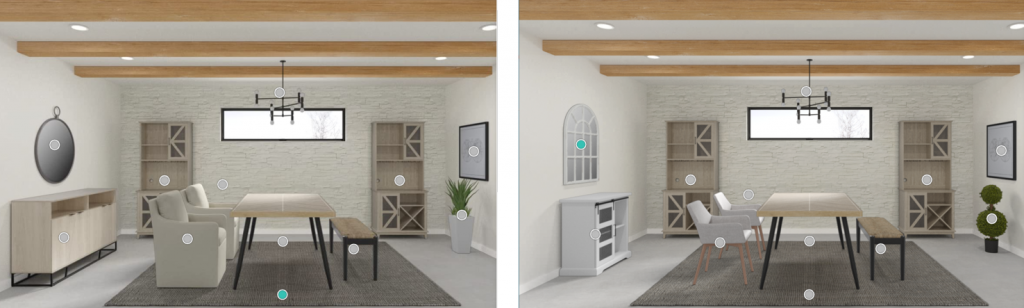
In 2009, we wrote an article highlighting some database challenges in a co-space environment [1]. In such an environment, the physical space and the digital space co-exist in a “universe” and applications can manipulate the data flow within and across the two spaces. 13 years have since passed and…
Read more…
by
Sebastian Link
on May 10, 2022 | Categories:
Big Data, Databases
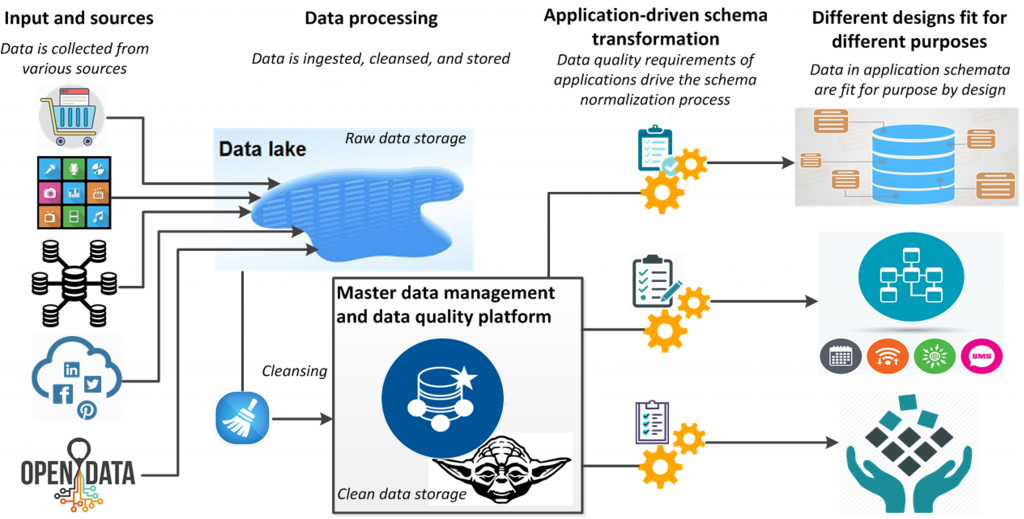
Financially, poor data quality costs organizations some ludicrous amounts of money. Worse, poor data quality is a strong inhibitor to the success of data science: No analytical method can create value from poor quality data. As a consequence, data science projects invest a majority of their…
Read more…
by
Mahsa Baktash and Zi (Helen) Huang
on Apr 17, 2022 | Categories:
Data Science, Machine Learning
Data as a major component of a deep learning solution is often undervalued in the ML projects, which results in a lower-than-expected accuracy, requiring hours and hours of model tuning. According to Andrew Ng, 99% of the recent publications are model-centric with only 1% being data-centric. He…
Read more…